ASE Studio and the gem5 backend
ASE Studio is a free educational application for learning RISC-V assembly, processor hazards, memory behaviour and instruction pipelines. You write a program, press Run, and see how every instruction flows through the processor, cycle by cycle.
Behind the graphical interface there is no hand-written "toy" model: every simulation is executed by gem5, the open-source microarchitectural simulator used in computer-architecture research worldwide. ASE Studio drives a version of gem5 modified by the CAD & Reliability research groups of Politecnico di Torino, and turns its detailed traces into the pipeline tables shown to students.
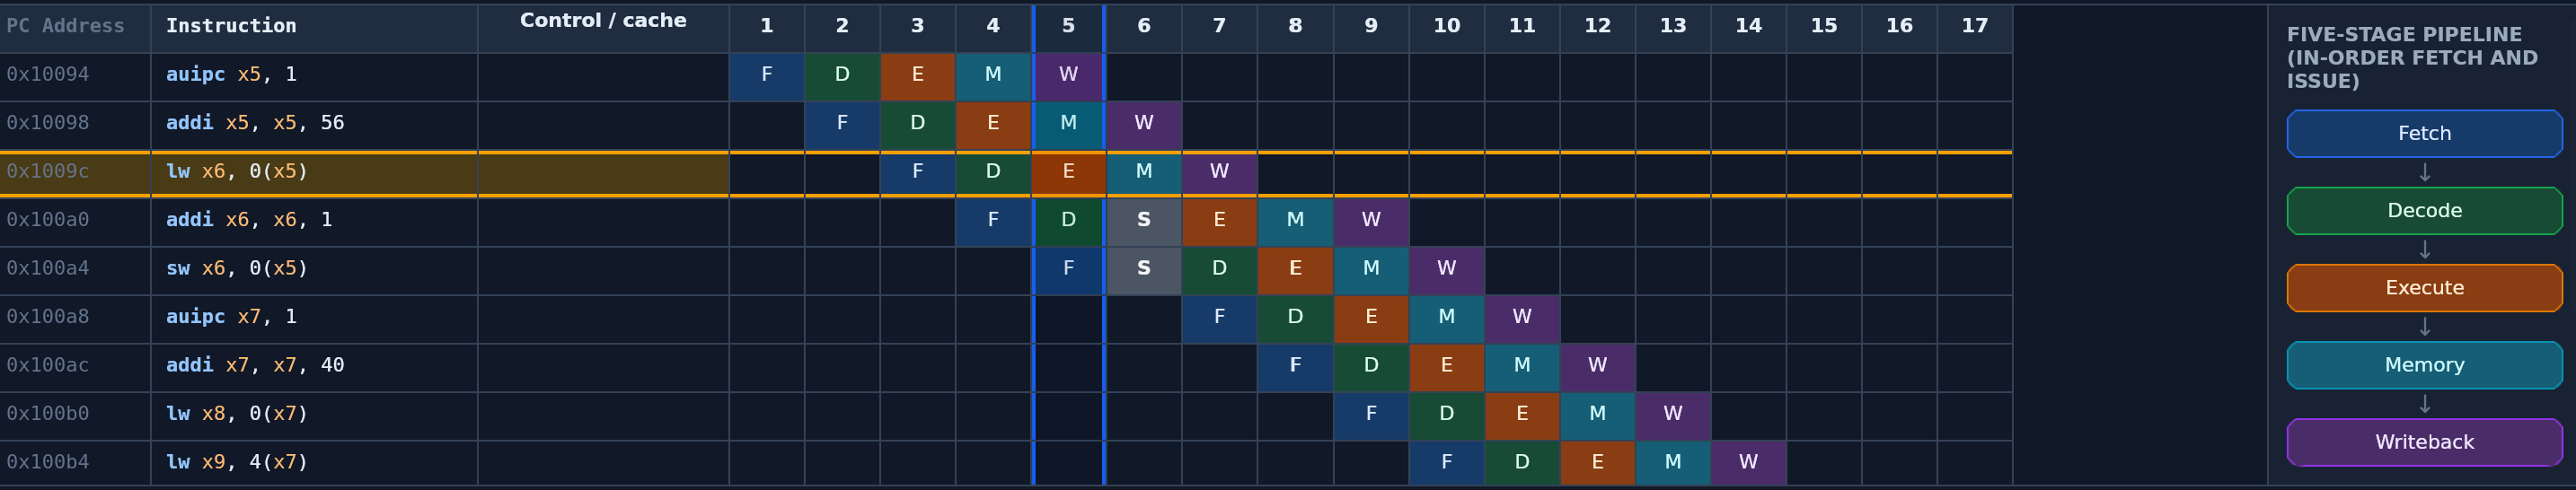
A five-stage in-order pipeline in ASE Studio: each row is an instruction, each
column a clock cycle; S marks a stall.
ASE Studio gem5 fork ase_riscv_gem5_sim
What is gem5
gem5 is a modular, event-driven computer-system simulator. Its building blocks — CPUs, caches, crossbars, memory controllers — are C++ objects (SimObjects) that exchange timed messages through ports. The system to simulate is not hard-coded: it is described by a Python configuration script that instantiates the components, sets their parameters and connects them.
Key concepts used by ASE Studio:
| Concept | Meaning |
|---|---|
| ISA | gem5 is built for a target instruction set; ASE Studio uses the RISC-V build (gem5.opt, an optimised binary that keeps debug tracing). |
| CPU models | gem5 offers several processors with different accuracy/speed trade-offs: Atomic/Timing simple (functional), MinorCPU (in-order pipeline) and O3CPU (out-of-order superscalar). ASE Studio uses the last two. |
| Syscall Emulation (SE) | The program runs "bare" on the simulated CPU: gem5 loads the ELF and emulates the operating-system calls itself, so no Linux image is needed. |
| Debug flags | Switches that make gem5 print a detailed log of internal events; ASE Studio parses this log to build the pipeline view. |
| Statistics | At the end of the run gem5 writes stats.txt with hundreds of counters (cycles, committed instructions, cache misses, branch mispredictions…). |
From your code to the pipeline view

- Build — the program is compiled with a RISC-V GCC cross-compiler
(
riscv*-elf-gcc) with optimisations disabled (-O0), so the executed code matches what you wrote;objdumpprovides the disassembly. - Configure — the settings chosen in ASE Studio (CPU type, latencies,
forwarding, memory, widths, predictor…) are passed as
--ase-…options to the gem5 Python configuration script. - Simulate — gem5 runs the ELF in SE mode with debug tracing enabled.
- Visualise — ASE Studio parses the trace: for every dynamic instruction it
records the cycle in which it enters each stage, the register values it
writes (
Execflag) and the stalls, and draws the table. Summary figures (cycles, CPI, branch mispredictions) come fromstats.txt.
In-order model: the five-stage pipeline
The default processor is gem5's MinorCPU, an in-order pipelined core,
configured (riscv_in_order_hen_patt.py) to behave like the classic
five-stage RISC pipeline of Hennessy & Patterson:
| Stage | What happens | |
|---|---|---|
| F | Fetch | The instruction is read from instruction memory. |
| D | Decode | Operands are read; the instruction waits here if an operand is not yet available (RAW hazard → stall S). |
| E | Execute | The instruction runs in a functional unit; loads/stores compute their address. |
| M | Memory | Loads and stores access data memory. |
| W | Writeback | The result is written to the register file. |
The fork adds a dedicated debug flag, MinorGUI, which logs each
instruction's passage through these stages in a form the visualiser can read.
The core is narrowed to a single-issue pipeline (one instruction per stage,
one-entry buffers between stages, no idling), so hazards appear exactly as in
the textbook.
Functional units
Execution uses six functional units. For each one ASE Studio lets you set the latency (cycles in Execute) and whether it is pipelined (a new instruction can enter every cycle) or not (it must wait until the previous one finishes). Defaults of the in-order model:
| Unit | Instructions | Latency | Pipelined |
|---|---|---|---|
| Integer ALU | arithmetic/logic, address calculation | 1 | yes |
| Integer multiplier | mul… |
1 | yes |
| Integer divider | div…, rem… |
1 | yes |
| FP adder | fadd.s, fsub.s… |
2 | yes |
| FP multiplier | fmul.s |
7 | yes |
| FP divider | fdiv.s |
8 | no |
Long-latency units make structural and data hazards visible: a
dependent fadd.s right after an fmul.s has to wait for the multiplication,
and two consecutive fdiv.s cannot overlap.
Forwarding
Forwarding (bypassing) can be switched on or off:
- on — a result is passed directly from the end of Execute to the next instruction, which can enter Execute on the following cycle;
- off — a dependent instruction must wait until the producer has reached Writeback, so stalls become longer and easier to count.
Memory
Two memory models are available:
- Direct memory — the CPU is connected to an ideal memory through delay elements with separate, configurable instruction-read, data-read and data-write latencies. With latency 1 the access fits exactly in the F or M stage; higher values add stall cycles.
- Cache — gem5's timing L1 instruction and data caches are inserted, with configurable size, line size and hit latency (default 2 cycles), backed by a deterministic memory with a configurable miss penalty (default 30 ns). Hits and misses are modelled by gem5; DRAM bank/row variability is deliberately left out so results are reproducible.
Out-of-order model: superscalar pipeline
Selecting the out-of-order CPU switches to gem5's O3CPU
(riscv_o3_custom.py), a superscalar core with register renaming, a reorder
buffer and speculative execution. Its pipeline stages are Fetch, Decode, Rename,
Dispatch/Issue, Execute, Writeback and Commit; the trace comes from gem5's
standard O3PipeView flag.
| Parameter | Default |
|---|---|
| Fetch / decode / rename / dispatch / issue / writeback / commit width | 2 instructions per cycle |
| Reorder buffer (ROB) | 64 entries |
| Instruction queue (IQ) | 128 entries |
| Load queue / store queue | 32 / 32 entries |
| Physical registers | 80 integer, 64 floating-point |
| Functional-unit latencies | int ALU 1 · int mul 3 · int div 8 · FP add 6 · FP mul 8 · FP div 4 (not pipelined) |
All widths and queue sizes are configurable, so you can observe how the instruction window and the issue width affect the achieved parallelism (IPC).
Branch prediction
The out-of-order core fetches speculatively past branches. The predictor can be chosen among gem5's implementations:
| Predictor | Idea |
|---|---|
| Local | 2-bit saturating counters indexed by the branch address. |
| Tournament | Local and global predictors with a chooser that learns which one to trust. |
| Bi-Mode | Separate tables for mostly-taken and mostly-not-taken branches to reduce aliasing. |
| TAGE | Tagged tables indexed with geometrically increasing history lengths — state of the art. |
| Ideal | Teaching mode: the trace is produced with a real predictor but no misprediction penalty is applied. |
Mispredicted branches appear in the view as squashed wrong-path instructions,
and their count (condIncorrect) is reported with the statistics.
Results and statistics
After every run ASE Studio reports, from gem5's stats.txt:
- cycles and committed instructions,
- CPI (cycles per instruction),
- branch mispredictions (out-of-order model),
together with the final register values, and can export the results as CSV.
Command-line use
The same simulations can be run without the GUI from the
ase_riscv_gem5_sim
repository (branch ase_studio):
./simulate.sh -i ./programs/my_program -nogui
The setup_default file selects the toolchain, the gem5 build and the CPU
configuration script; results (trace, stats.txt, logs) are written to
results/<program>/. Besides the configurable out-of-order core, the repository
contains two ready-made variants: riscv_o3_simple.py (32 kB L1 caches, LTAGE
predictor) and riscv_o3_two_level_caches.py (adds a 256 kB L2 cache).
Limits of the model
Programs run in syscall-emulation mode, without an operating system or peripherals, and memory timing is deterministic. These simplifications are intentional: they keep the results reproducible and focused on the processor microarchitecture.